LLM Model Routing: Choose by Task, Risk and Cost
Choose from eligible models
Validate the output outside the model
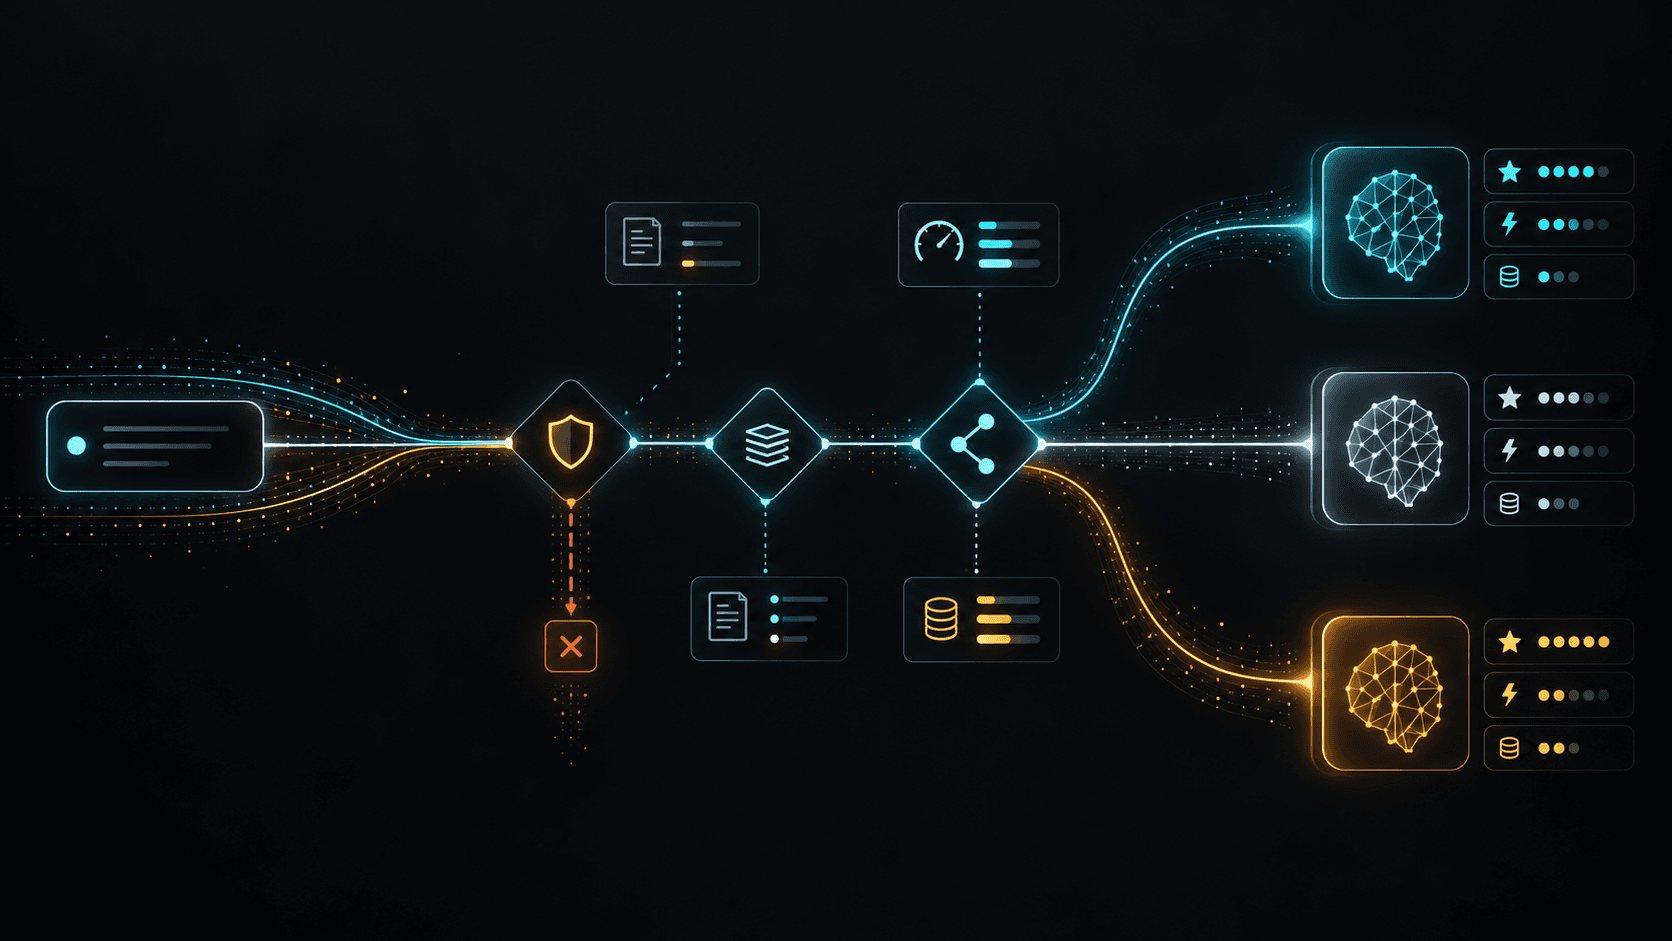
Original seven-stage architecture
Task, policy, budget and recovery
$ route --contract ROUTE-GATE-7
> bind: task / data class / budget
> filter: eligible models / regions
> rank: quality / latency / cost
> route: accept / fallback / reviewModel routing chooses a model for a particular request under an explicit quality, latency, cost and safety contract. It is more than picking the cheapest provider on each call. A route is useful only when the application can explain why it chose a model, detect an unsuitable result and recover without silently changing the task's meaning.
This guide addresses the narrow question of LLM model routing. For broader system design, see prompt engineering, AI automation and AI specialist in Armenia. Related production concerns include structured outputs and prompt versioning.
Problem and requirements
A support workflow receives short classification requests, grounded summaries and sensitive escalation drafts. Sending every request to one expensive model can waste budget; sending every request to a small model can fail quality or policy requirements. A router needs an explicit task class, data sensitivity, required output schema, deadline, budget ceiling, approved model list and fallback policy. These fields are supplied by trusted application code, not guessed from an arbitrary document or model response.
The decision target is not an abstract model leaderboard. It is a task-specific acceptance gate: the answer must satisfy a known schema and evidence requirement, fit an acceptable response time and stay within an authorized cost envelope. Some requests should not be sent to any model until access or human review is resolved.
Original architecture: ROUTE-GATE-7
The following seven-stage design is an illustrative architecture, not a measured customer deployment:
- Bind the request. Authenticate the caller and record the task class, tenant, allowed data, deadline and maximum spend.
- Apply hard policy. Exclude models and destinations that cannot handle the data or required output. A low price cannot override this gate.
- Read a versioned registry. Each candidate records its provider, model version, region, capabilities, price basis, rate limits and known operational constraints. Retire stale entries deliberately.
- Rank eligible candidates. Use task-specific evaluation results and observed latency/cost distributions. Treat a score as evidence for a defined test set, not as universal quality.
- Execute with limits. Set timeouts, token and retry budgets and a stable request identifier. Never turn an ambiguous external write into an automatic second action.
- Validate the output. Check schema, required citations or facts, policy and route-specific acceptance criteria outside the model.
- Route the result. Return, retry within a bounded compatible pool, ask for clarification or send to human review. Record the decision, model version and outcome without storing unnecessary sensitive text.
A useful dependency map is trusted request → policy filter → candidate registry → ranked selection → bounded call → validator → response/review. The policy filter and validator belong to the application. The LLM cannot grant itself eligibility or certify its own output.
Minimal decision example
Assume three hypothetical model profiles: fast for structured labels, balanced for ordinary grounded summaries and reviewed for complex drafts. These are roles, not real vendor measurements. A ticket tagged sensitive=true is routed only to profiles approved for that data class. If none is eligible, the result is hold, even when the request has a tight deadline.
const request = bindTask(actor, input, { deadlineMs: 2500, maxCost: 0.02 });
const eligible = registry.current().filter(model =>
  policy.allows(model, request.dataClass) &&
  model.supports(request.schema) &&
  model.estimatedCost(request) <= request.maxCost
);
if (eligible.length === 0) return holdForReview("no_eligible_model");
const candidate = rankByTaskEvidence(eligible, request.taskClass)[0];
const output = await callWithBudget(candidate, request);
if (!validate(output, request.schema, request.evidence))
  return routeCompatibleFallbackOrReview(request, candidate);
return recordDecisionAndRespond(output, candidate.version);
The cost value is a synthetic ceiling to show the contract, not a recommended price. Real token pricing, latency and model behavior change. Set them from a versioned registry and measure them in the target workload.
Components and contracts
Task classifier. Prefer deterministic signals such as endpoint, form field and workflow stage. If a model classifies the task, validate its label and allow an unknown route. Record classification errors separately from answer errors.
Eligibility policy. Check data residency, permissions, tool capabilities, context size and output support before ranking. Avoid sending sensitive content to a candidate merely to discover that it is ineligible.
Evaluation set. Keep representative normal, edge, multilingual, long-context and adversarial examples. For each fixture, define expected route, schema, evidence and forbidden behavior. Compare candidate and baseline on the same fixture versions.
Runtime telemetry. Capture route, candidate version, input/output token counts where available, latency, validation result, fallback reason and final outcome. Aggregate by task class and data class. Do not treat provider success or HTTP 200 as proof that the user's task succeeded.
Failure modes and recovery
A price-only router may choose a model that fails citations or formatting, making retries more expensive than a suitable first call. A latency-only router may prefer a quick but inadequate answer. Version drift can invalidate old evaluation scores while a model name appears unchanged. Provider outages and rate limits can force a fallback whose data handling or capabilities differ. A failed validation can be caused by bad evidence or a missing permission rather than model weakness; repeating with a stronger model will not fix those inputs.
A fallback must pass the same hard policy and output contract. After an ambiguous tool action, reconcile the destination by operation ID before retrying. If the output is high consequence or the eligible pool is exhausted, route to human review with a clear reason. Keep a last-known-good routing policy so a bad registry or weight change can be rolled back independently of a model deployment.
Testing and production check
Start with an offline replay of versioned fixtures. Assert both route selection and final acceptance: allowed model, schema, citations where required, cost ceiling, deadline behavior and denied-data handling. Include empty evidence, malformed output, timeout, rate limit, provider 5xx, stale registry and a model version change. Test the fallback chain without real external writes.
Then run a limited shadow or canary comparison on permitted traffic. Observe quality failures, p50/p95 latency and actual billed usage by task class. Declare thresholds before looking at results; compare against a baseline with the same inputs. Do not publish an invented savings or accuracy percentage. Promote only when the candidate passes the agreed checks and rollback has been exercised.
The production contract is a versioned policy plus measured evidence. A router is successful when it chooses an eligible model, returns an accepted result within limits, and makes failures legible. To review such a design for your workflow, request an architecture audit.
const task = bindTask(actor, input, limits);
const eligible = registry.filter(model => policy.allows(model, task));
if (!eligible.length) return holdForReview();
const output = await callWithBudget(rank(eligible, task)[0], task);
return validate(output, task) ? accept(output) : fallbackOrReview();