RAG Retrieval Metrics: Recall, Precision and Context Relevance
Measure whether the right evidence arrives before judging generated prose
Declared corpus, expected evidence, top-k results and slice-level inspection
Original RETRIEVAL-METRICS-8 example with limits, not a model score
RAG retrieval metrics, recall, precision, context relevance, retrieval evaluation and grounded AI systems
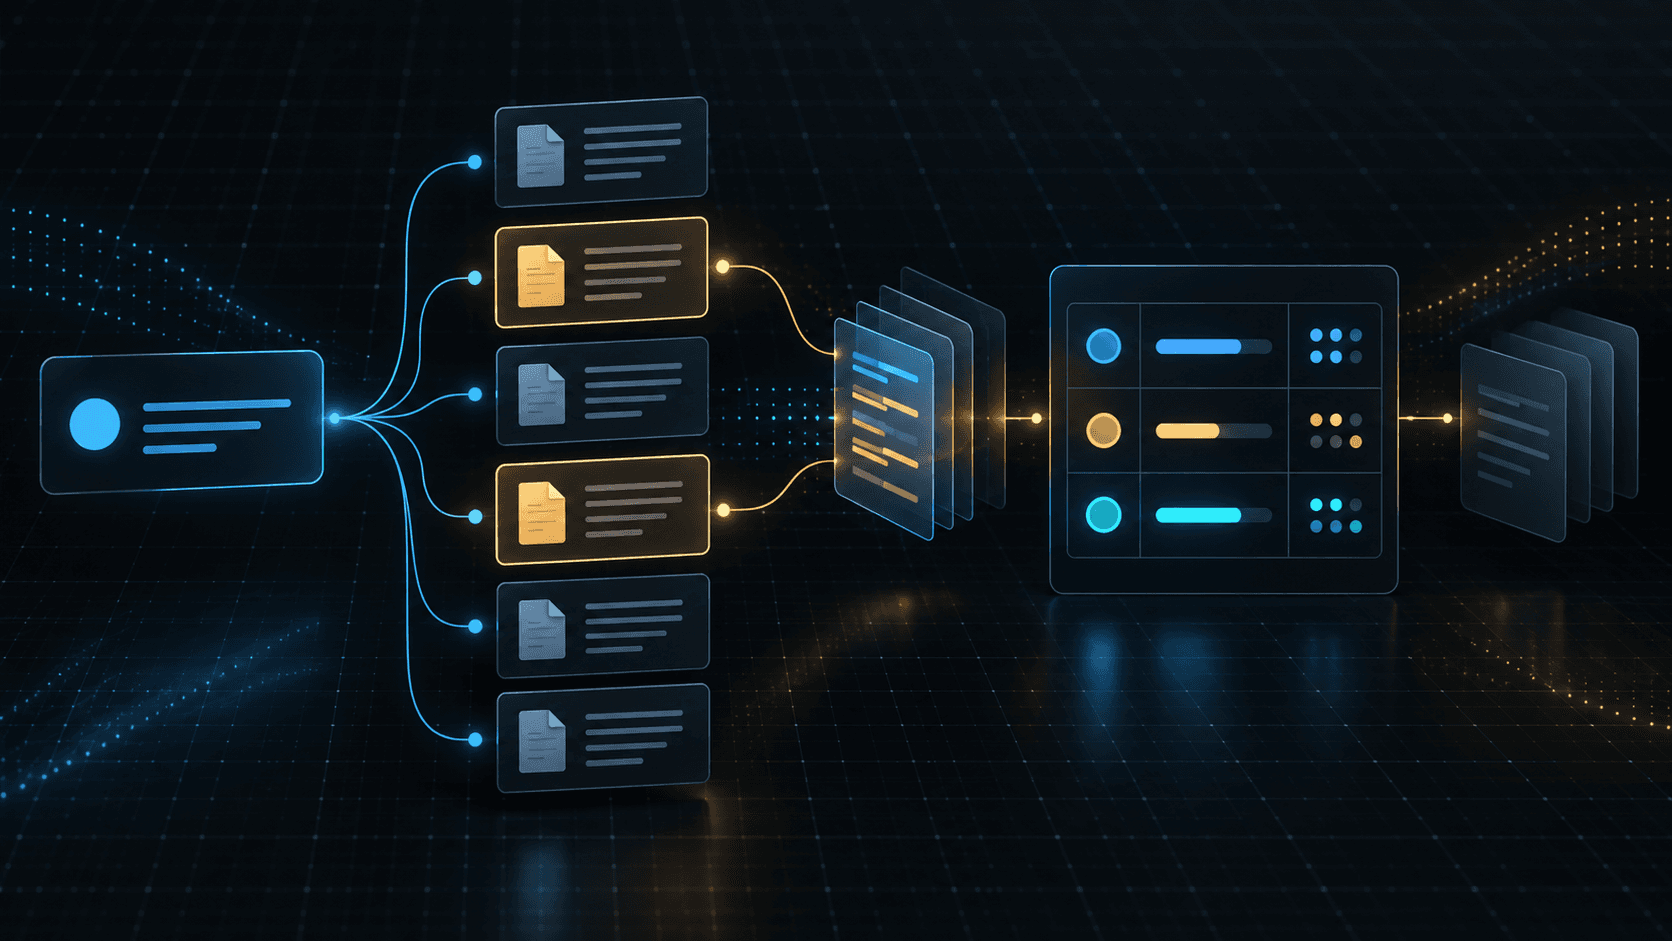
$ inspect-retrieval --contract RETRIEVAL-METRICS-8
> bind: question / permitted corpus / expected evidence
> retrieve: top-k candidates / filters / index version
> measure: recall / precision / context relevance by slice
> route: improve retrieval / clarify scope / hold release / reviewRetrieval is a separate decision from generation
A RAG answer can sound fluent while the retrieval step selected the wrong evidence. That is why recall, precision and context relevance are useful: they inspect the hand-off between a question and the context supplied to a model. They are not a universal score, and none of them proves that a final answer is safe by itself.
The practical unit of evaluation is a declared case: a question, the permitted corpus and its version, the evidence that should be discoverable, a top-k setting, and an expected safe route. Without that contract, two people may calculate the same-looking number over different documents and mean different things.
Three metrics, in plain language
Retrieval recall asks: did the system retrieve the evidence needed for this question? If a current policy paragraph should have been in the candidate set but is absent, recall is poor for that case. Recall does not mean that every returned passage is useful.
Retrieval precision asks: of the passages returned, how many help answer this specific question? A system can retrieve the needed paragraph and ten unrelated pages. That can yield good recall and poor precision: the right evidence is present, but the model receives distracting context.
Context relevance asks whether the context actually supplied to the answering step is relevant and sufficient for the task. It is close to the question a reviewer asks when reading a trace: “Could this context support the requested statement?” It is not a substitute for factual verification, access checks, citations or expert review.
A single running example
Imagine an employee asks: “Which travel expenses require manager approval?” The current policy has one applicable clause; an older policy has a similar, superseded clause; and the corpus also contains expense templates and general company news.
For this case, record the current clause as expected evidence. Run the exact query with the same trusted role, locale, filters, index version and top-k used by the product. Then inspect the returned locators.
| Observation | What it tells you | First action |
|---|---|---|
| Current clause is absent | Recall failure, or a corpus/filter/query problem | Check source lifecycle, access filter, chunking and query formulation |
| Current clause appears with many unrelated cards | Recall may be adequate; precision is weak | Narrow scope, improve metadata filters or add reranking |
| Only the superseded clause appears | Freshness and lifecycle failure, not a “better prompt” problem | Remove or demote retired evidence before ranking |
| Current clause appears but lacks the approval condition | Context is incomplete for the claim | Change chunk boundaries or retrieve the linked section |
This is why one aggregate number is rarely enough. Keep the case result together with its retrieved locators and source revisions so that a regression can be reproduced rather than guessed from a chat transcript.
How a small evaluation loop works
- Select real question shapes, including ambiguous questions, no-answer cases and questions with expected current evidence.
- Declare the permitted corpus and source snapshot. Exclude retired, private or out-of-scope material before measuring ranking.
- Write expected evidence as stable locators or IDs, not only as an ideal answer sentence.
- Run retrieval with the real filters, index version and top-k. Save the retrieved locator list.
- Inspect recall, precision and context relevance by useful slices: document type, language, role, freshness state or question family.
- Route the failure to the responsible layer: source coverage, lifecycle, access, chunking, query, filters, ranking, answer policy or human review.
The purpose is not to chase a cosmetic percentage. It is to make the next engineering decision inspectable.
Where these metrics help—and where they do not
They help when a team has a bounded corpus, a repeatable question set and a reason to distinguish retrieval problems from answer-generation problems. They are especially useful before comparing prompts or changing models, because a missing source cannot be repaired by more confident prose.
They do not establish legal, medical, financial or safety correctness. They do not validate permissions, decide whether a source is authoritative, measure user satisfaction, or guarantee that a cited answer interpreted a document correctly. Those need their own controls and qualified review.
| Suitable use | Not sufficient for |
|---|---|
| Regression checks after an index or chunking change | A public claim that a model is “accurate” |
| Comparing retrieval configurations on the same declared cases | Replacing access control or source ownership |
| Finding a stale source that entered top-k | Approving consequential advice or external action |
| Identifying a question family that needs a safe no-answer route | Treating an aggregate score as a customer outcome |
Minimal RETRIEVAL-METRICS-8 record
The following synthetic record illustrates the fields worth keeping. It is a method example, not a benchmark or a performance result.
{
  "case_id": "policy-approval-current-01",
  "question": "Which travel expenses require manager approval?",
  "permitted_corpus": "policy-snapshot-2026-09-10",
  "expected_locators": ["travel-policy:v4#approval"],
  "run": {
    "index_version": "idx-42",
    "filters": ["role:employee", "locale:en", "state:current"],
    "top_k": 5,
    "retrieved_locators": ["travel-policy:v4#approval", "expenses-guide:v2#receipt"]
  },
  "review": { "route": "inspect-precision-before-release" }
}
If travel-policy:v4#approval is missing, investigate coverage, lifecycle, filters and retrieval before judging the answer. If it is present but surrounded by irrelevant context, investigate precision and context packaging. If the user’s role or request is not sufficient, route to clarification or a safe no-answer instead of silently broadening retrieval.
A practical next step
Start with ten to twenty cases that correspond to real recurring questions and failure reports. Version the cases and sources, preserve the trace, and review changes by slice before release. That creates a shared language for product owners and engineers: a failure is no longer only “the RAG answered badly,” but a specific evidence-selection problem with a visible next owner.
For a broader system design, see the RAG systems service guide and the AI specialist in Armenia page. This article supports those service pages with retrieval-evaluation criteria; it does not replace their broader commercial intent.
require(case.question && case.permittedCorpus && case.expectedEvidence);
require(run.indexVersion && run.retrievedLocators && run.topK);
require(metrics.slices.every((slice) => slice.denominatorIsDeclared));

if (expectedEvidence.isMissing) route = "fix-corpus-or-label-no-answer";
if (retrieval.scopeIsWrong) route = "repair-filter-before-tuning-ranking";
if (precision.low && recall.high) route = "rerank-or-narrow-context";
if (recall.low) route = "inspect-coverage-query-and-retrieval";