Reduce LLM Latency Without Losing Control
Measure time to accepted answer
The fast route retains validation
Original LATENCY-GATE-6 design
Illustrative budget, no measured speedup
$ latency --contract LATENCY-GATE-6
> trace: queue / retrieve / infer
> gate: source / schema / policy
> route: accept / reviewA faster model call does not necessarily make a useful answer arrive sooner. Retrieval, tool calls, validation, retries and human review can dominate the full path. This guide focuses on end-to-end LLM latency: time from an accepted request to a verified response or an explicit handoff. It is an architecture example, not a benchmark or a promise of measured savings.
For the broader service context, see AI specialist in Armenia, prompt engineering and AI automation. Related decisions are covered in model routing and the evaluation suite. Here the narrow question is where to shorten the critical path while preserving the same acceptance rules.
Problem and requirements
Define the response contract before optimizing: permitted data, source freshness, response schema, critical refusal rules and the deadline. Measure time to first useful token and time to accepted answer separately. A streamed sentence that is later rejected does not meet the latter measure. Segment the trace by queue wait, retrieval, reranking, model inference, tool execution, validation and retries. Record p50 and p95 for each segment under the same workload; a mean hides slow requests.
A design budget is a set of limits, not observed performance. For example, a team might allocate 150 ms to queue and policy checks, 300 ms to retrieval, 1,500 ms to the primary model, 200 ms to validation and 350 ms to a reserve. Those numbers are illustrative and must be replaced by measurements on the actual stack. The reserve matters because an apparently fast happy path can become slow when a validator or tool fails.
Architecture: LATENCY-GATE-6
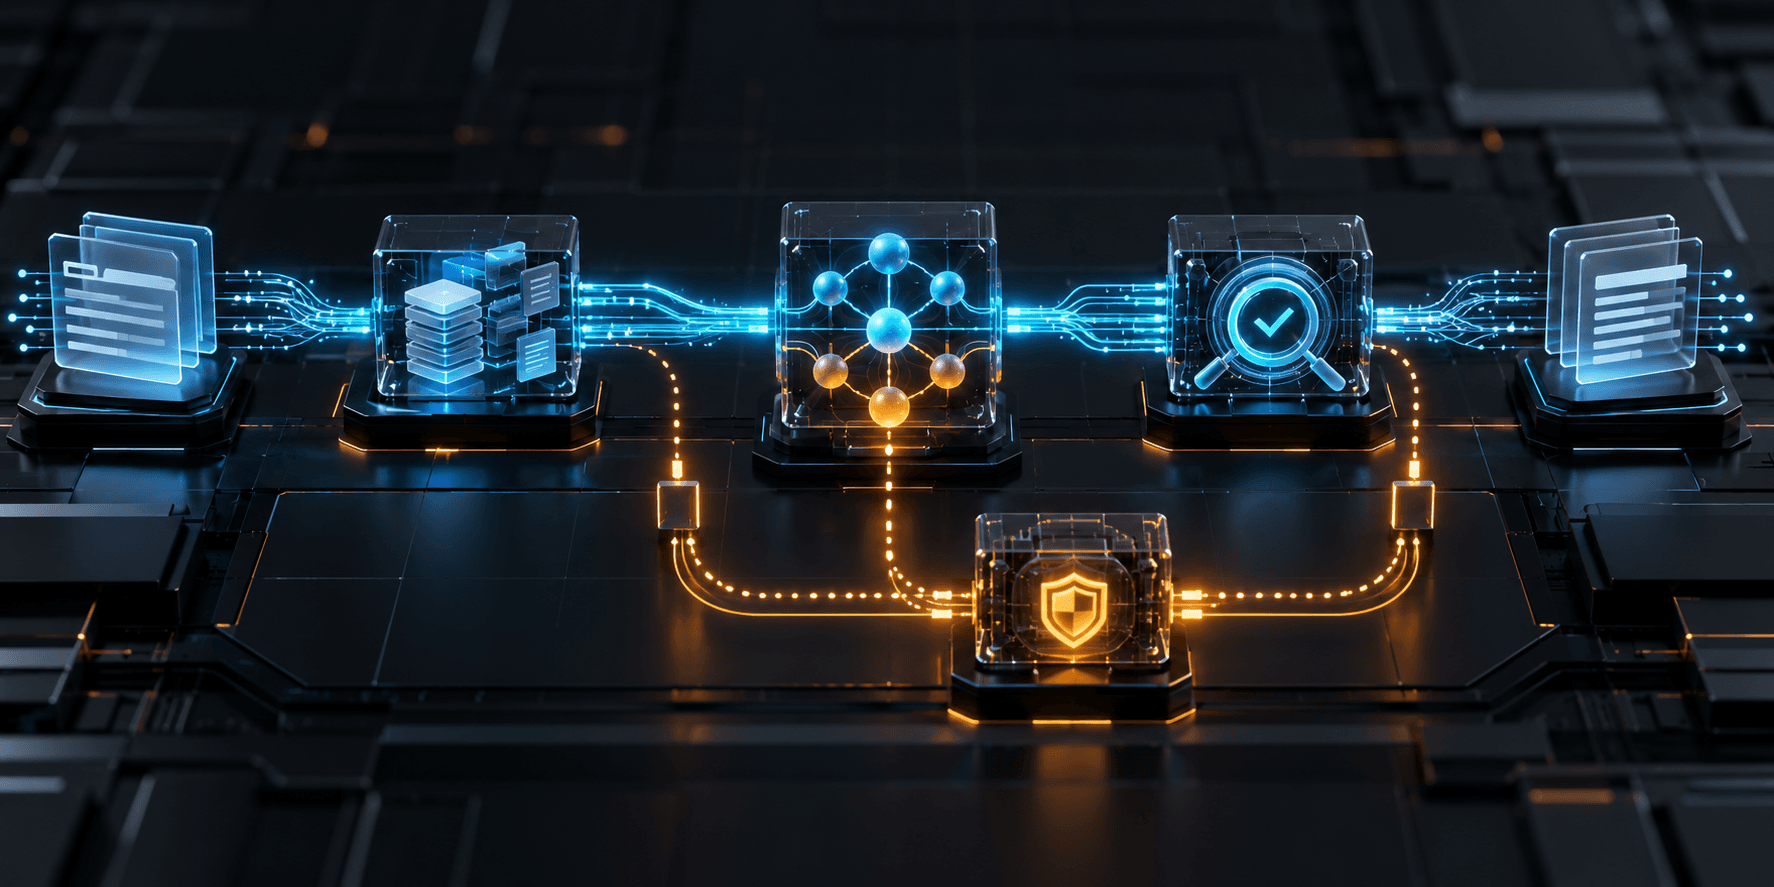
The following original LATENCY-GATE-6 contract is a minimal design example. It places cheap eligibility checks before expensive work and keeps the final safety gate outside the model. Each transition produces a trace span and a reason code. The route never skips source authorization or response validation to meet a deadline.
REQUEST → scope/policy gate → retrieval snapshot ─┬→ eligible fast route → validation → ACCEPT
                                                   └→ complex route → validation → ACCEPT
                                                           ↓ failure or deadline
                                                    bounded fallback / REVIEW
The request carries tenant scope, task class, deadline, idempotency key and source version. The router chooses only among models already approved for that task and data class. Retrieval returns source IDs and revisions. The validator checks schema, citations, current source and prohibited actions. If a critical gate fails, the system refuses or hands off; it does not silently serve a faster unchecked answer. A fallback gets at most one bounded attempt under the same policy.
Component contracts
| Component | Input and output | Latency lever | Control that stays in place |
|---|---|---|---|
| Queue | Request ID → admitted job | Bound concurrency and reject overload early | Preserve fair tenant quotas and deadline |
| Retrieval | Scoped query → versioned evidence | Parallel independent reads; trim irrelevant context | Enforce access and freshness before ranking |
| Router | Task class and evidence → eligible route | Use a cheaper fast route on proven task classes | Gate by policy and evaluation results |
| Model | Pinned prompt and context → candidate | Stream output; cap output length by task | Never treat partial output as accepted |
| Validator | Candidate and evidence → accept/review/refuse | Deterministic schema and source checks | Keep critical checks independent of model |
| Fallback | Reason code → bounded retry or review | Retry only recoverable faults | Reconcile unknown tool effects before replay |
Pseudocode: a bounded critical path
The snippet below is executable-style pseudocode, not a library integration. deadline.remaining() uses a monotonic clock. The model route has no permission to change the validator or expand tenant scope.
const trace = beginTrace(request.id);
const scope = await authorize(request.actor, request.tenant, request.task);
if (!scope.allowed) return refuse("scope_denied", trace);

const evidence = await retrieveScoped(request.query, scope, request.sourceRevision);
if (!evidence.fresh) return review("stale_source", trace);

const route = chooseEligibleRoute(request.task, scope.dataClass, evaluationVersion);
const candidate = await callModel(route, evidence, {
  deadline: request.deadline,
  maxOutputTokens: route.taskLimit,
  promptVersion,
});
const verdict = validate(candidate, evidence, scope, responseSchema);
if (verdict.accepted) return accept(candidate, trace);
if (verdict.critical || request.deadline.remaining() < fallbackReserve)
  return review(verdict.reason, trace);
return retryOnceOrReview(request, evidence, verdict, trace);
Failure modes and recovery
A cache can remove inference time but return an answer from an outdated source. Key it by tenant, task, permissions, prompt and source revision; invalidate on document or policy changes. For a critical answer, validation still checks the returned source. Parallel retrieval can reduce wall time but multiply load and leak data if access filters differ between branches. Apply the same scope to every branch and cancel work after the deadline.
Streaming improves perceived responsiveness but cannot certify a complete answer. Display partial text as provisional until validation succeeds, or use a UI that clearly withholds action controls. Hedged model requests may improve tail latency but increase cost and duplicate tool effects. Limit them to read-only inference; use an idempotency key and reconciliation for external actions. An indiscriminate retry after timeout can worsen p95 and duplicate work. Retry only classified transient failures within a reserve, and record unknown outcomes for review.
A faster model may pass superficial format checks while failing groundedness or critical refusal cases. Reuse the versioned evaluation suite for the actual task before routing traffic. A short context may reduce inference time while removing decisive evidence. Compare accepted-answer rate and reviewer load alongside latency, using the same source snapshot.
Testing and production check
Build traces for each stage with request ID, task class, route, source revision, prompt version and verdict. Exclude secrets and personal content from ordinary telemetry. Run representative short and long requests, empty retrieval, stale sources, malformed outputs, a slow tool, timeout and overload. Test cold and warm paths separately. Report p50/p95 time to accepted answer, accepted-answer rate, critical-gate failures, retry count and cost per accepted answer by task class. Never infer a production improvement from the illustrative budget above.
Before rollout, freeze a baseline, acceptance rubric and a maximum permitted regression for quality, p95 latency, cost and review volume. Stage the eligible route for a limited cohort, compare on the same workload, and keep the prior route ready. If the safety gate or source freshness fails, stop promotion even when p95 improves. For a technical review, send an anonymized trace and acceptance criteria: the useful input is a request path, stage timings, source versions and failure examples, not a claimed speedup.
if (!scope.allowed || !evidence.fresh) return review;
const candidate = await callEligibleRoute(deadline);
const verdict = validate(candidate, evidence, scope);
return verdict.accepted ? accept(candidate) : review(verdict.reason);