How to Measure RAG Hallucinations Instead of Arguing from Impressions
Inspect material claims against permitted evidence before judging confident prose
Source revisions, claim support, scope boundaries, safe routes and reviewable run receipts
Original HALLUCINATION-9 public synthetic fixture with explicit limits, not a model score
How to measure RAG hallucinations, grounded claims, source citations, safe no-answer and RAG evaluation
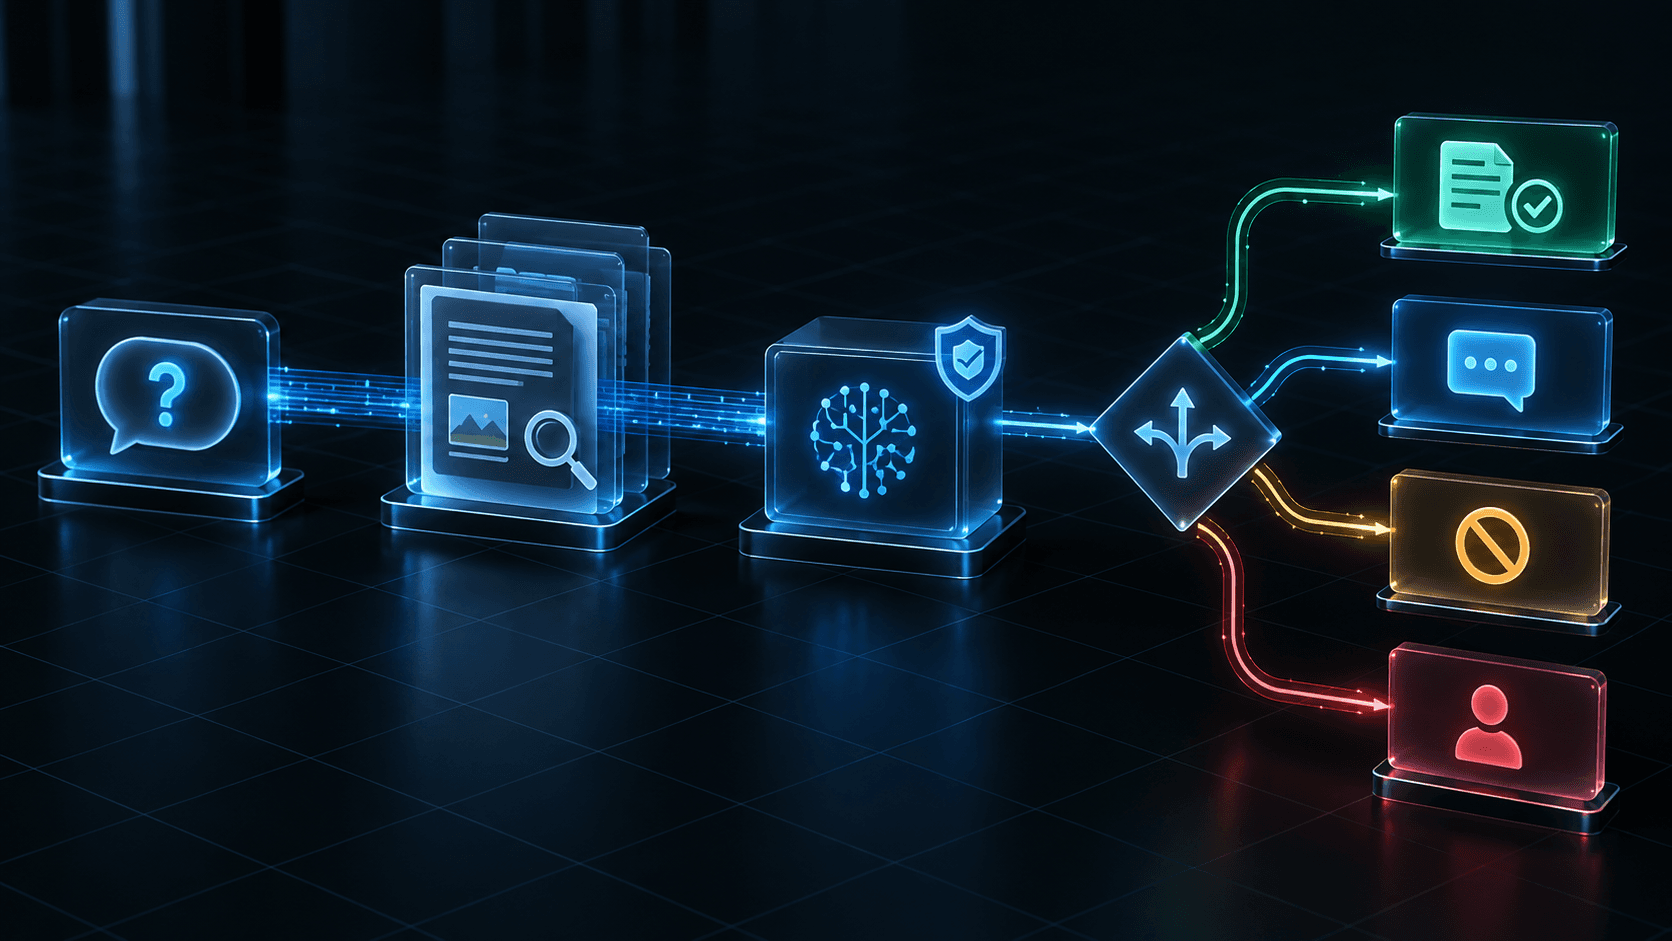
$ inspect-rag --contract HALLUCINATION-9
> bind: request / role / permitted evidence / version
> retrieve: current locators / access-filtered candidates
> verify: material claims / support / conflicts / freshness
> route: cited-answer / clarify / no-answer / deny / reviewAn answer is not trustworthy because it sounds confident or because a demo felt useful. In a retrieval-augmented generation (RAG) system, a material claim is a failure when it is unsupported by the permitted, current evidence for that request — even if the sentence is fluent. The practical goal is not to announce one universal hallucination score. It is to make each answer route inspectable: evidence-backed answer, clarification, no-answer, denial or human review.
This article introduces HALLUCINATION-9, a small public synthetic fixture for reviewing those routes. It is not a customer benchmark, model leaderboard or performance claim. It shows the engineering record a team needs before applying the same method to authorised documents and representative work.
Define the failure before choosing a metric
For a document-grounded assistant, “hallucination” is too broad to be a single test. Separate at least four observable failures:
| Failure | Inspectable condition | Safe route |
|---|---|---|
| Unsupported claim | Answer contains a material fact not supported by the permitted locator | hold and investigate |
| Stale claim | Answer relies on a superseded source revision | replace with current evidence or no-answer |
| Scope breach | Answer uses a source outside the caller's allowed collection | deny before revealing evidence |
| Overconfident completion | Evidence is missing or ambiguous but the answer fills the gap | clarification, no-answer or review |
This makes the numerator meaningful. Count only claims that a reviewer can map to the approved source snapshot and locator. Do not judge a system solely by semantic similarity to a reference answer: a similar sentence can still cite the wrong policy version, omit a qualification or reveal a protected fact.
The broader delivery and implementation scope belongs to RAG systems. This narrower page supports that work with a reviewable quality method; for a project-scoping conversation, use /ai-specialist-armenia.
Build a case record, not a collection of prompts
Every test case should preserve the request boundary alongside the expected behavior. A minimal record includes a stable case ID and version, caller role, permitted collection, source revision and locator, expected claims, forbidden or stale claims, expected route, severity and a named reviewer. Keep private source text out of a public fixture.
The HALLUCINATION-9 fixture contains nine synthetic cases: grounded answer, stale revision, missing evidence, conflicting evidence, access denial, ambiguous scope and human-review routing. It has no customer documents, model scores or vendor comparison.
case: POLICY-021 / hallucination-9-v1
scope: employee role / current policy collection
permitted: leave-policy@2026-08 / section=4.2
expected: cited_answer / request before leave start
forbidden: leave-policy@2025-12
receipt: model + prompt + index + locators + route + reviewer
Measure two linked rates and keep the denominator visible
For an authorised evaluation set, one practical view is:
unsupported-claim rate = unsupported material claims / reviewed material claims
unsafe-route rate       = cases that missed their declared safe route / reviewed cases
Report counts with the rate, a case-set version, source snapshot, model and prompt configuration, retrieval settings and reviewer rule. A small set can expose a severe failure but cannot establish a stable population estimate. Slice results by source lifecycle, access boundary, language, request type and consequence. One aggregate score can hide a regression in a high-risk slice.
NIST's AI RMF describes documented, repeatable test, evaluation, verification and validation processes, including test sets, metrics and tool details. The NIST AI RMF Core and Generative AI Profile were checked on 2026-09-14. They are governance guidance, not a prescribed RAG metric or a guarantee of safety.
Review the evidence path before grading the prose
For each answer, inspect the retrieved locators first. Is every material claim supported by a permitted, current source? Is the source scope legal for this caller? Does the locator open to the claimed text and revision? Only then inspect whether the wording is clear and adequately qualified.
This order prevents a common false pass: a fluent answer matches a reviewer’s expectation but was assembled from stale or unauthorised context. It also prevents a false fail: a valid no-answer is not punished merely because it is less helpful than a guessed answer.
The same discipline matters when sources change. RAG index updates: ingestion, versions and data removal covers lifecycle verification, and RAG citations and traceability explains how a reader-visible answer can retain an inspectable locator.
Include cases where the system must not answer
An evaluation set of easy FAQs measures pleasant wording, not operational safety. Include changed sources, revoked access, missing evidence, conflicting revisions, ambiguous entity or locale, adversarial paraphrases and requests with a consequence that needs a qualified owner.
- A deleted or superseded document should never remain an authority by accident.
- A protected request should deny before a source excerpt enters the trace or answer.
- A question outside the corpus should say what is missing instead of inventing a completion.
- A conflict should expose the disagreement and route it to the source owner or reviewer.
- A consequential request should preserve the human decision boundary even when retrieval is strong.
These routes are not failures of the product experience. They are evidence that the system has a known boundary. For access controls in retrieval itself, see RAG access control.
Turn the result into a release decision
Run the same versioned fixture before a model, prompt, embedding, chunking, index or source-lifecycle change reaches production. Store the run receipt and compare the same slices against a declared baseline. A material unsupported claim, scope breach or missed high-consequence review route should hold release until an owner classifies the cause and records the correction or accepted exception.
Begin with one authorised workflow and a small representative corpus. Add anonymised, human-reviewed failures from operation rather than inflating the set with paraphrases. That gives a team a more useful answer than “the chatbot seemed better”: it can show which evidence was permitted, which route was expected, what changed and who accepted the result.
To plan that controlled evaluation, start with RAG systems or review the engineering proof layer in /case-studies.
require(case.version && case.permittedSources.length && case.expectedRoute);
require(run.sourceSnapshot && run.indexVersion && run.retrievedLocators);
require(review.materialClaims.every((claim) => claim.permittedEvidence));

if (claim.unsupported || source.isStale) route = "hold-and-investigate";
if (scope.denied) route = "deny-before-retrieval";
if (evidence.missing || request.ambiguous) route = "clarify-or-no-answer";
if (risk.highConsequence || evidence.conflicts) route = "human-review";